Sample teardown
Why two category pages on my own site were never crawled
Resin & Rolls (resinandrolls.com). Data current as of October 6, 2026.
Summary
Two category pages on resinandrolls.com, /category/printing-tutorials/ and
/category/materials-supplies/, have never been crawled by Google. I sent 82 Indexing API
submissions for them between May and August and got no crawl. I then found a likely contributor, sitemap
lastmod dates that were set to the build time, and fixed it on August 25.
As of today, October 6, both pages are still never crawled. The fix did not resolve this site's problem, and I do not yet know the full cause. This page shows how I diagnose the problem, what I have ruled out, and what I am still doing about it. Sources: Google Search Console URL Inspection (screenshots and API), my own submission log, the live sitemap, and the site's git history.
The symptom
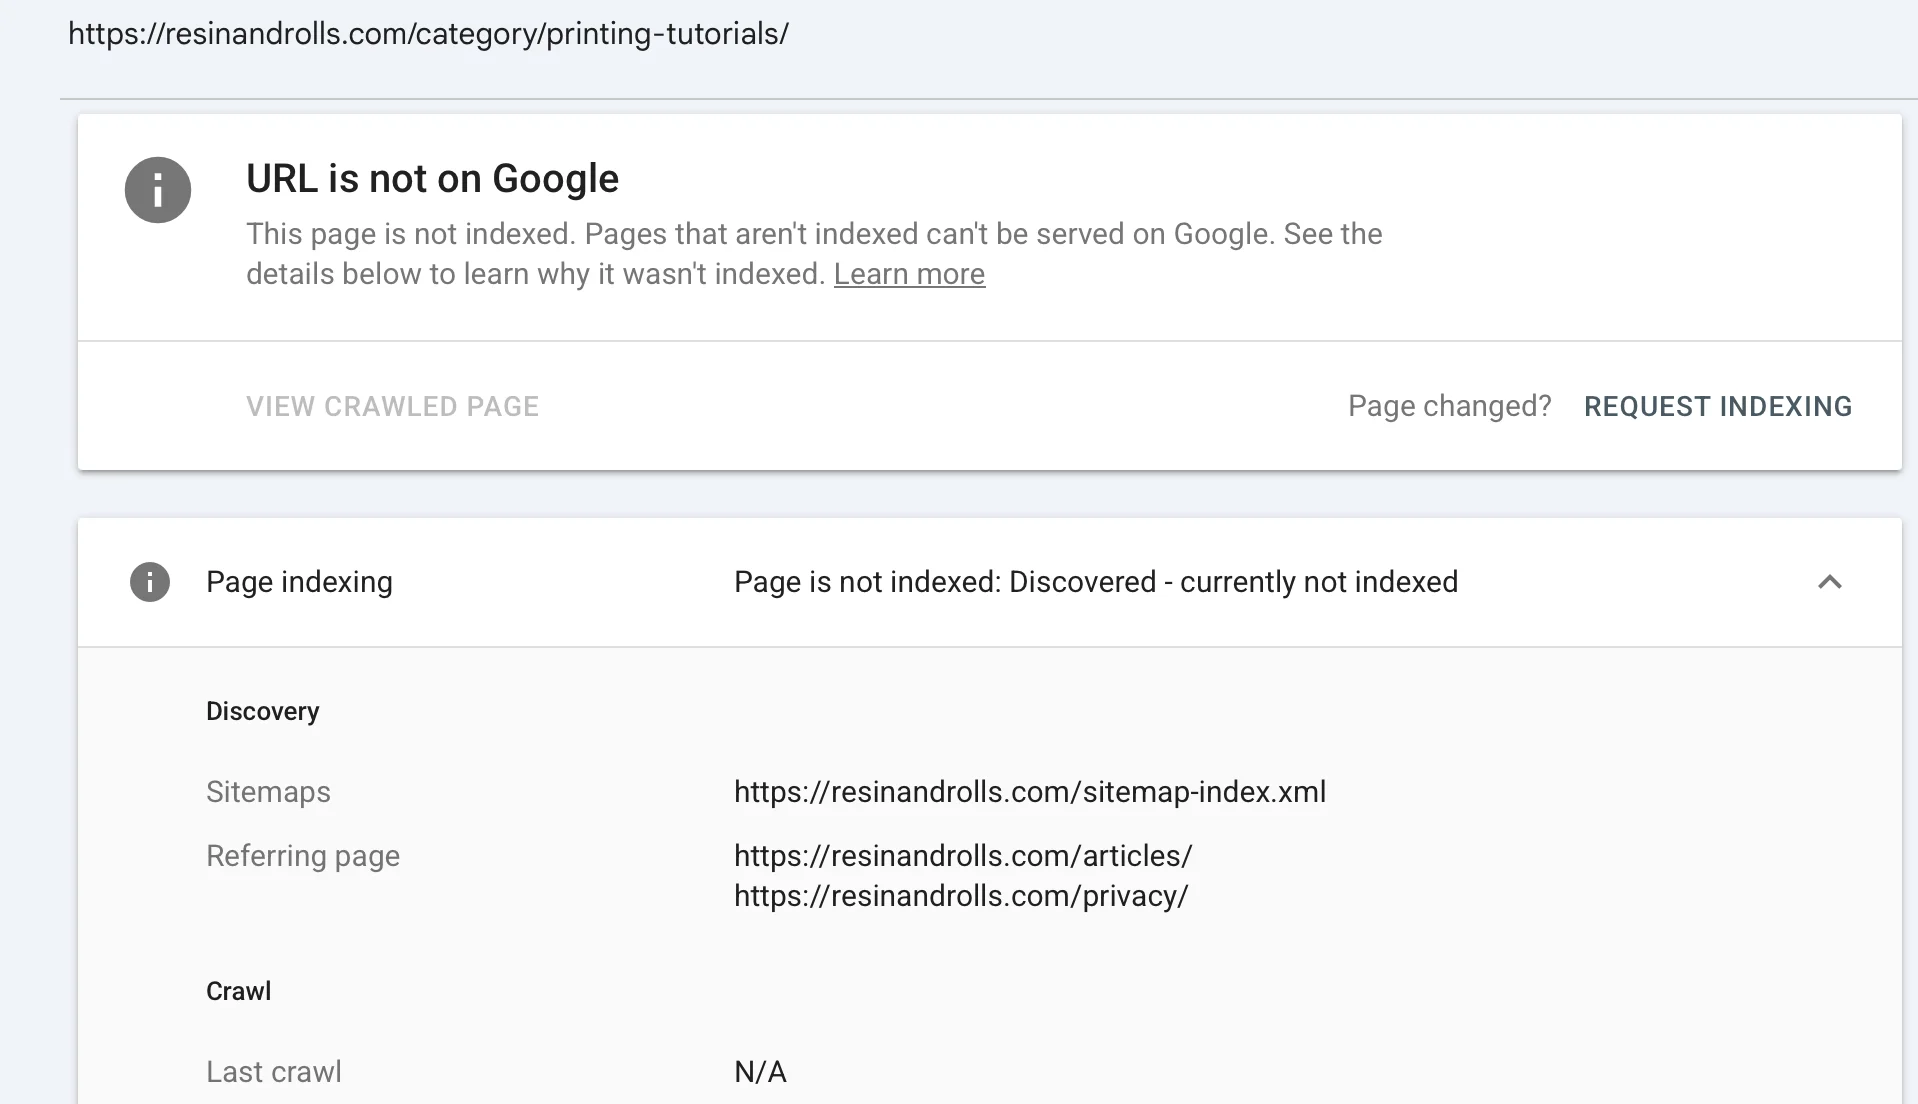
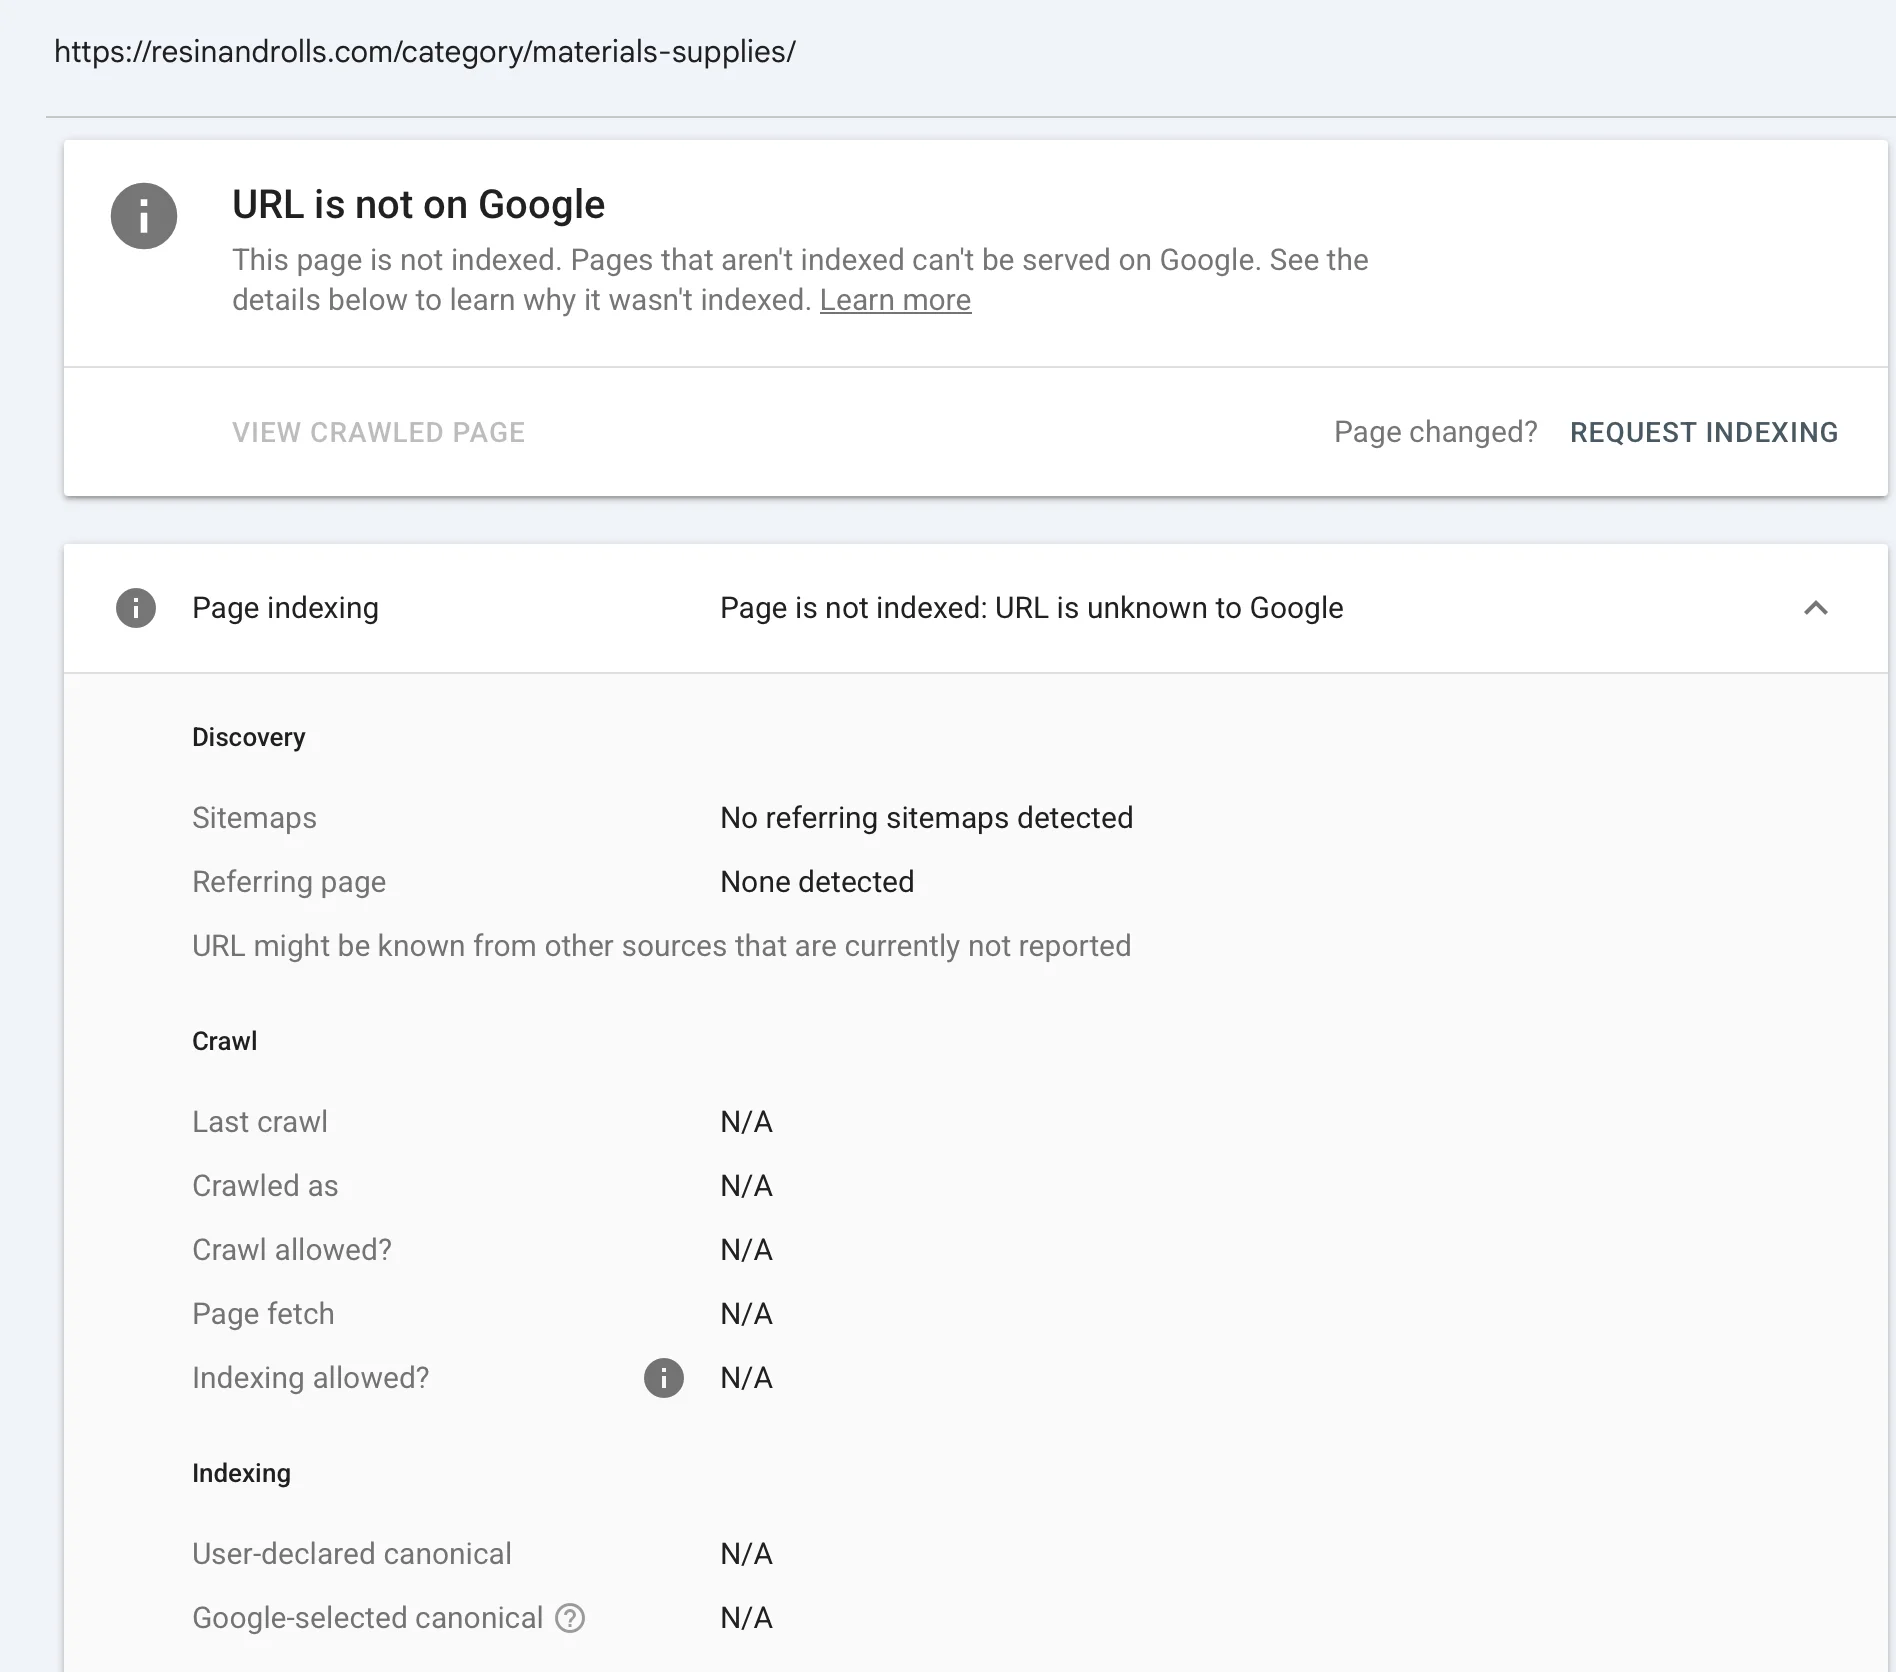
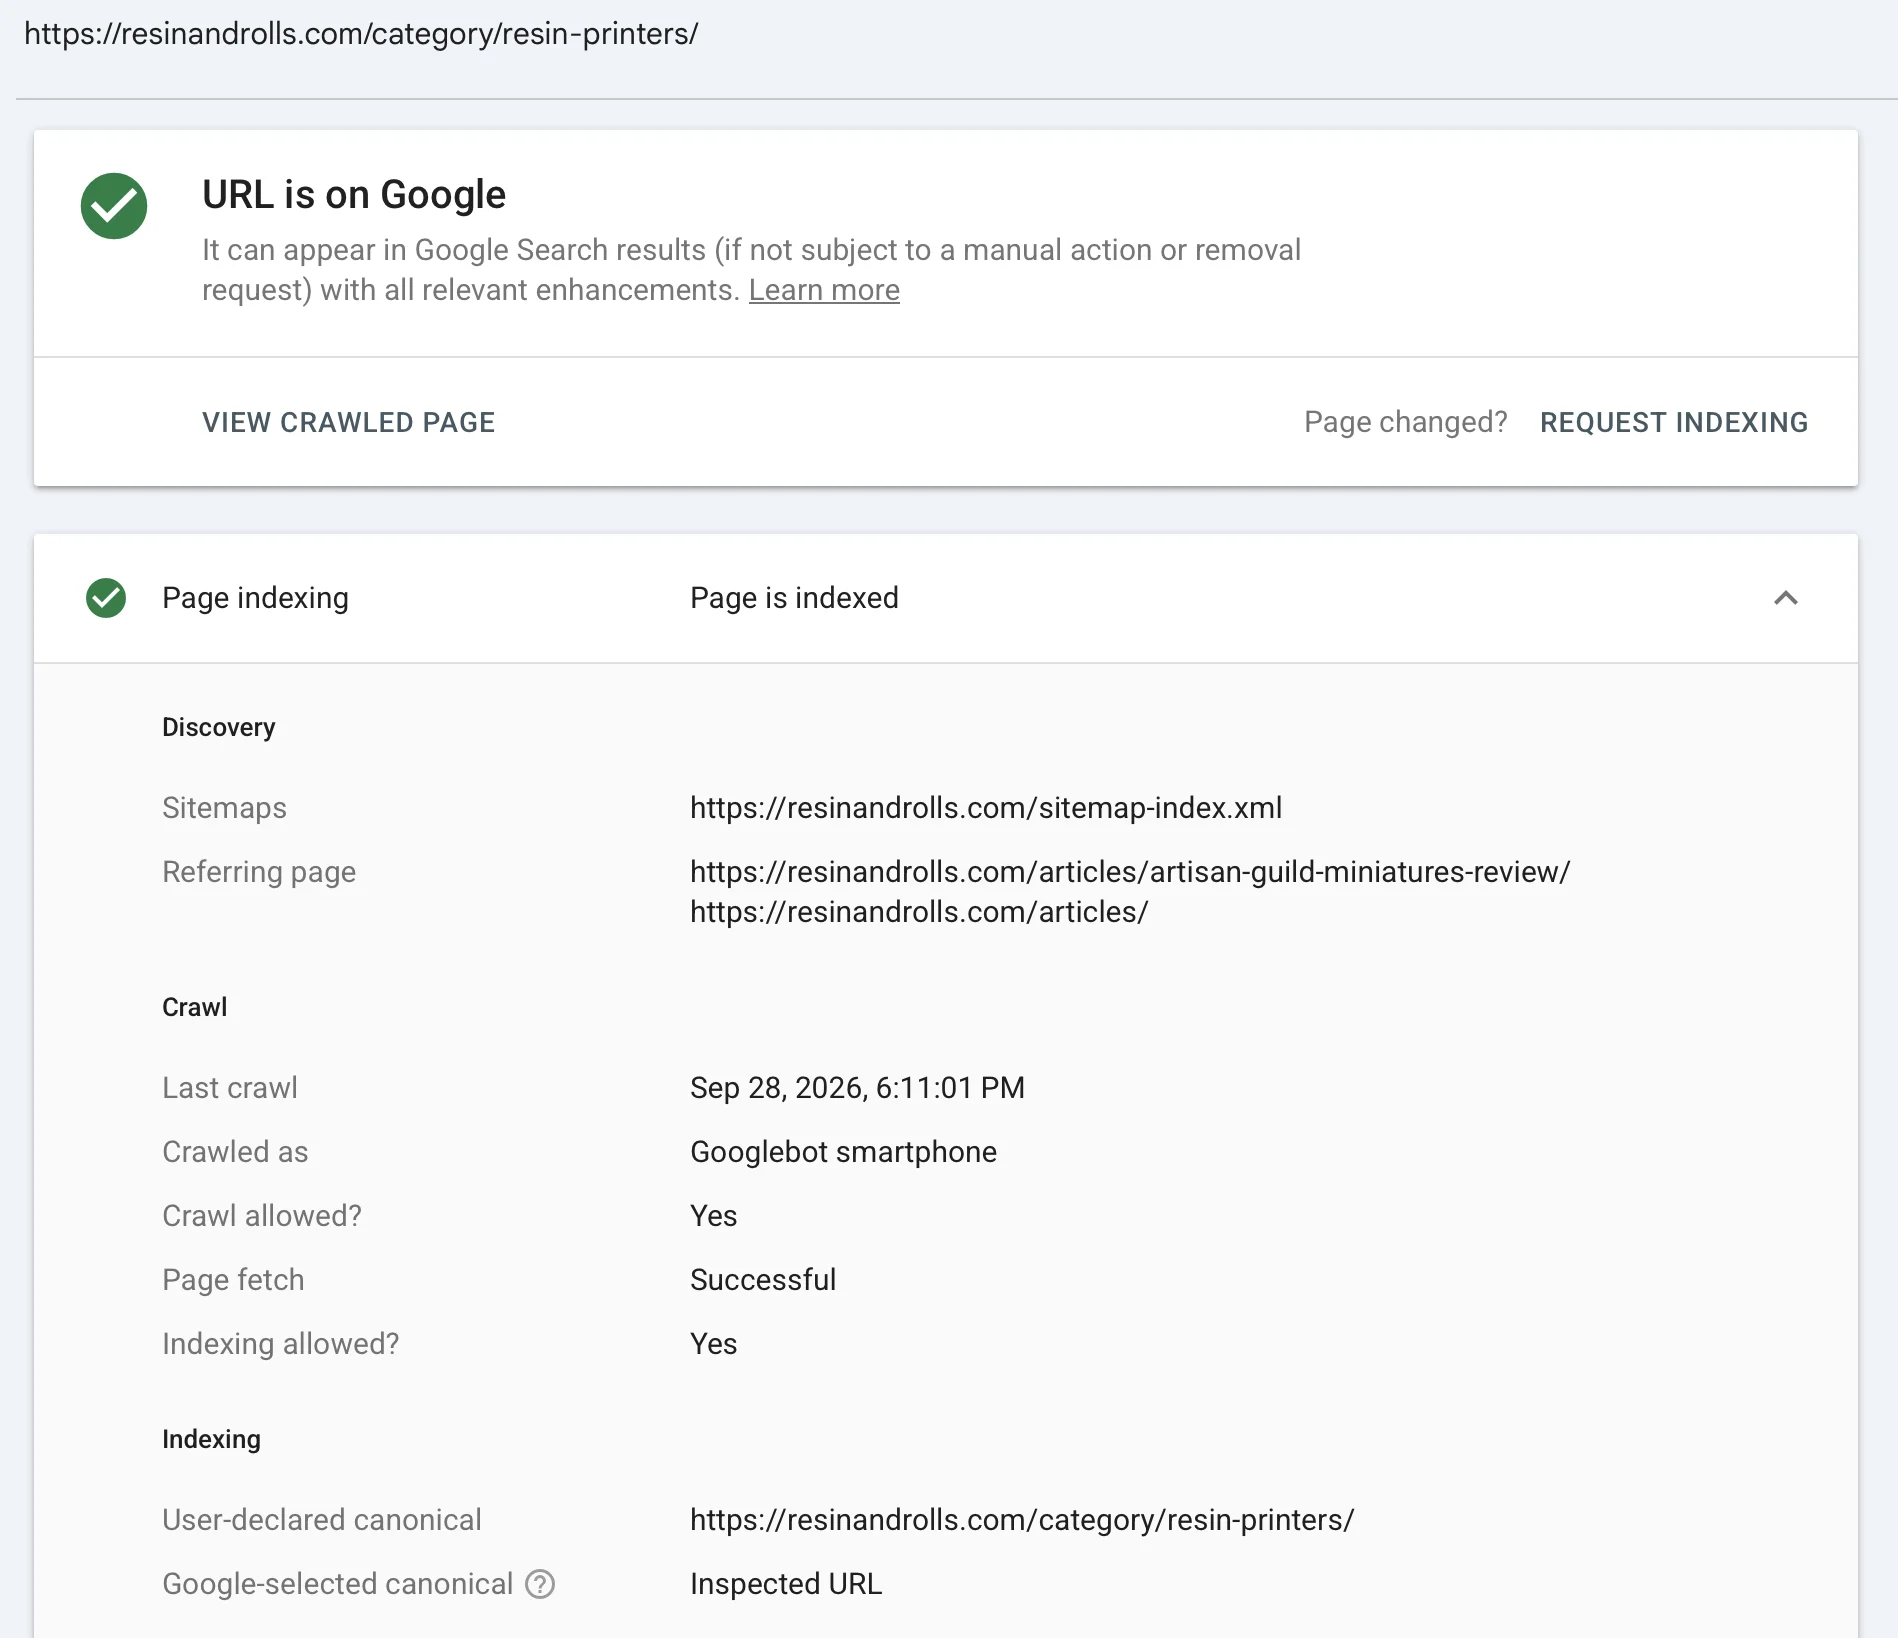
Two category pages sit at "not on Google" with Last crawl: N/A. A third category page on the same site, linked from the same places, is indexed and was last crawled on September 28.
The headline state is not trustworthy for never-crawled URLs
Look at the first two screenshots again. Both pages are listed in the same sitemap, return HTTP 200, and are
linked from /articles/. Search Console reports one as "Discovered - currently not indexed" and the
other as "URL is unknown to Google, no referring sitemaps detected". The second statement is wrong: the page is in
sitemap-0.xml, which sitemap-index.xml points to.
This is not a one-off. On August 24 I polled the URL Inspection API six times at 15-second intervals. For a never-crawled URL the status string alternated between "Discovered - currently not indexed" and "URL is unknown to Google", while the indexed control never changed. The status text is a presentation string, and it flips for pages Google has not crawled.
The stable signal is lastCrawlTime. It is absent on both pages and present on the control. Read that, not the headline. This matters because the two phrases suggest opposite fixes. "Unknown to Google" reads as a discovery problem (submit it, link to it). "Discovered" points at crawl scheduling. They describe the same state: Google may know the URL and has never fetched it.
What I ruled out, and how
Checks marked August 24 were run on that date; the others were re-run for this page.
- HTTP status and Googlebot access. Googlebot's user agent gets 200 on both pages (re-checked October 6, and on August 24).
- robots.txt.
Allow: /. Nothing blocks these paths. - Canonicals. Both pages carry a self-referencing canonical (re-checked October 6). No noindex tag.
- Noindex in the sitemap. Every category has published content and the sitemap filter was correct (August 24).
- Thin content. Printing tutorials is the largest category on the site, at 19 items (August 24). The indexed category I compared against had 8.
- Internal links from articles and guides. I counted links in the body of articles and guides, not the nav or footer, which link every category. Printing tutorials has 2, materials and supplies has 2, the indexed resin printers page has 1, and the indexed STL sources page has 0 (git history, October 6). Editorial links do not separate the crawled pages from the uncrawled ones.
The remedy that did not work, measured
From my own submission log: 42 Indexing API submissions for materials and supplies and 40 for printing tutorials between May 11 and August 21. Of those 82, 75 were acknowledged "ok" and 7 returned errors. None produced a crawl. Both pages still show no last crawl today. The API's "ok" is an acknowledgement that Google received the request, not evidence of a crawl.
Across the five category hubs on two of my sites that I was resubmitting, the August 24 count was 185 submissions over about three and a half months, all acknowledged, none crawled. Here is what has happened since, so the figure is not read as current. The log now holds 187 submissions for those hubs. The three ErgoDeskGuide hubs have since been crawled and indexed, on September 14 and 15, after the same sitemap fix. For two of them (accessories and monitors and arms), a new submission had been sent about two and a half and three and a half hours before the crawl on September 15, so I cannot separate the submission from the fix there. The third was crawled on September 14 with no submission since August 21. The two Resin & Rolls hubs got no crawl.
That is the basis for what I sell and what I do not. I do not sell indexing submission. I look for why Google is skipping the page.
A likely contributor: sitemap lastmod
The site's sitemap generator took lastmod from git history only for articles and guides. Every
category page, tag page, the homepage and static pages fell back to the build time. Google was told those pages
changed on every build, about four times a week, so the signal carried no information.
On August 24 I inspected 72 Resin & Rolls sitemap URLs. Of the 25 with build-time dates, 14 (56%) had never been crawled. Of the 47 with real git dates, 13 (28%) had never been crawled. A second site showed the same direction: 5 of 13 (38%) against 4 of 50 (8%).
| Site | lastmod source | URLs | Never crawled |
|---|---|---|---|
| Resin & Rolls | Build-time fallback | 25 | 14 (56%) |
| Resin & Rolls | Real git date | 47 | 13 (28%) |
| ErgoDeskGuide | Build-time fallback | 13 | 5 (38%) |
| ErgoDeskGuide | Real git date | 50 | 4 (8%) |
The limit of this evidence: it is a correlation across 72 URLs on one site, with the same direction on a second. It is strong enough to act on and not a controlled experiment. And 13 of the never-crawled Resin & Rolls URLs already had correct dates, so lastmod is not the whole story.
The fix, and where it stands today
Sitemap lastmod now comes from real git history for every URL, and is omitted rather than invented when
git cannot supply a date. The change was merged on August 25, 2026. The live sitemap now carries dates for all 92 of
its URLs, and those dates are stable between builds.
Result so far: mixed. The three ErgoDeskGuide hubs were crawled within three weeks. The two Resin & Rolls hubs are still uncrawled six weeks later. Across the whole Resin & Rolls sitemap, 28 of its 92 URLs (30%) have no last crawl today, against 27 of 72 (38%) on August 24. The sitemap has grown since, so the two figures are not a like-for-like comparison. I am reporting the state as it is, not the state I hoped for.
Does this apply to a WordPress site?
This finding came from an Astro build. On WordPress, lastmod normally comes from each post's modified
date, and the analogous failures are plugins or themes that touch modified dates on bulk updates, or SEO plugins that
stamp the same date on archive pages. I have not yet seen this on a client WordPress site. What I claim is the method:
I check lastmod accuracy and crawl state, using lastCrawlTime, as part of every Diagnosis.
What I would still fix on this site
- The two category pages are still uncrawled. I have stopped resubmitting them and read lastCrawlTime weekly.
-
There are 16 near-duplicate
/tag/pages in the sitemap. ErgoDeskGuide blocks its tag routes and has better crawl coverage, which is suggestive and not proof. Whether to block or consolidate Resin & Rolls' tag pages is a content decision that has not been made. - Search Console once reported a tag page as "blocked by robots.txt" while the live robots file allows everything. I have not explained that discrepancy.
The deliverable format
A Diagnosis ends in a ranked table like this one, with a URL, the evidence, the fix and a severity for every item. These rows are from this site and use today's data.
| URL | Evidence | Fix | Severity |
|---|---|---|---|
/category/printing-tutorials/ and /category/materials-supplies/ | Last crawl N/A on October 6. 82 submissions, no crawl. Fix merged August 25, no change yet. | Stop resubmitting. Read lastCrawlTime weekly. Decide the tag-page question below, then re-test. | Important |
/tag/* (16 pages) | Near-duplicates of category pages. A sister site that blocks tag routes crawls better (not proven). | Decide: block, noindex, or consolidate. Measure lastCrawlTime on the category pages afterward. | Important |
Sitemap lastmod | Build-time dates on 25 of 72 URLs, 56% never crawled against 28% for real dates. | Real git dates, omitted when unknown. Done August 25. | Done |
Want this for your site?
The Diagnosis is $395, fixed price, built on your own Search Console data.